
FLUX Kontext Paper: Summary, PDF, and Portrait Edits
Find the FLUX Kontext paper and PDF, understand its architecture and KontextBench findings, and see two sequential portrait edits with exact prompts.
The FLUX Kontext paper is Black Forest Labs’ research report on image generation and editing with text and image references: FLUX.1 Kontext: Flow Matching for In-Context Image Generation and Editing in Latent Space, arXiv 2506.15742. It explains how Kontext preserves subjects through successive edits. You can try that workflow in the Kontext editor on flux-3image, an independent app running BFL models.
Where can you read the FLUX Kontext paper?
As of October 2026, arXiv lists the first submission as June 17, 2025, and the latest revision, v2, as June 24, 2025. Open the v2 PDF for the complete report.
Start with Section 3 for the architecture, Section 4.1 for KontextBench, and Section 4.3 for repeated edits. Figure 11 shows a head-angle change followed by an expression change—the workflow illustrated below.
How does Kontext combine an image with an instruction?
Kontext encodes the reference and output images as latent tokens: compressed representations of visual information. It places those tokens in one sequence so the model can use the reference alongside your instruction. The paper’s implementation uses one context image. The framework also supports text-only generation, although Kontext [dev] was trained specifically for image editing. Section 3 describes these distinctions.
What does KontextBench measure?
KontextBench contains 1,026 image-and-prompt pairs drawn from 108 base images. It covers local edits, whole-image edits, text replacement, style references, and character references. The authors report strong local editing, text editing, and character preservation results. Sections 4.1 and 4.2 describe the benchmark and findings.
For repeated edits, Section 4.3 uses face-embedding similarity to measure changes in facial identity across a sequence. That gives the paper’s consistency claim more support than selected pictures alone. These results describe the authors’ 2025 evaluation; they do not establish a ranking against today’s models. See the iterative-editing evaluation.
What survives a head turn followed by a smile?
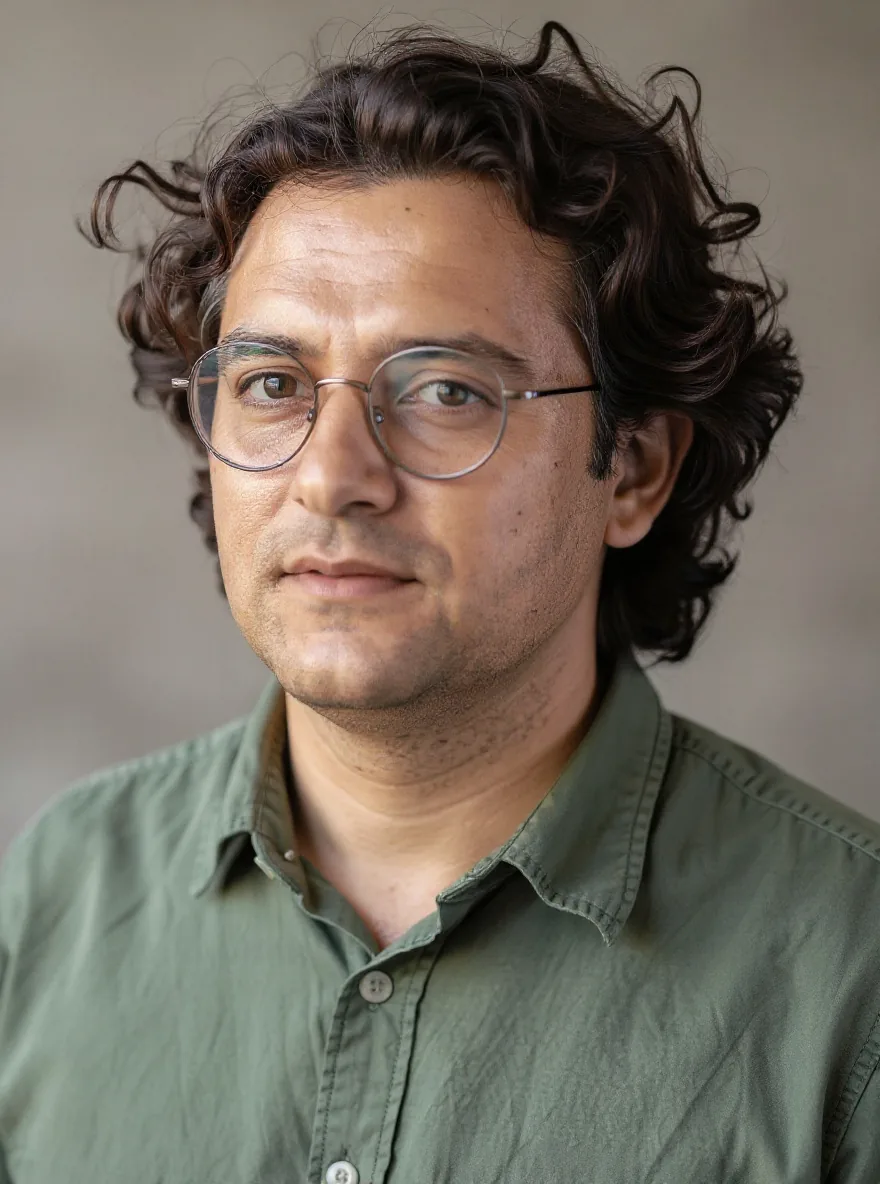
Our input is a fictional adult man generated with FLUX.2 [pro]. We applied two FLUX.1 Kontext [pro] edits, using the first output as the second edit’s reference. Each request used one image, default output sizing, and the exact instruction below, with prompt enhancement off. This sequence illustrates repeated editing; it does not reproduce the paper’s benchmark or measure face similarity.
First instruction, applied to the original:
Turn his head slightly to his left while keeping both eyes visible. Preserve his identity, glasses, hair, shirt, lighting and background.
Second instruction, applied to the head-turn result:
Make him smile naturally with his mouth closed. Keep his head angle, face shape, glasses, shirt, lighting and background unchanged.
| Original portrait | Head-turn result | Smile from the head-turn result |
|---|---|---|
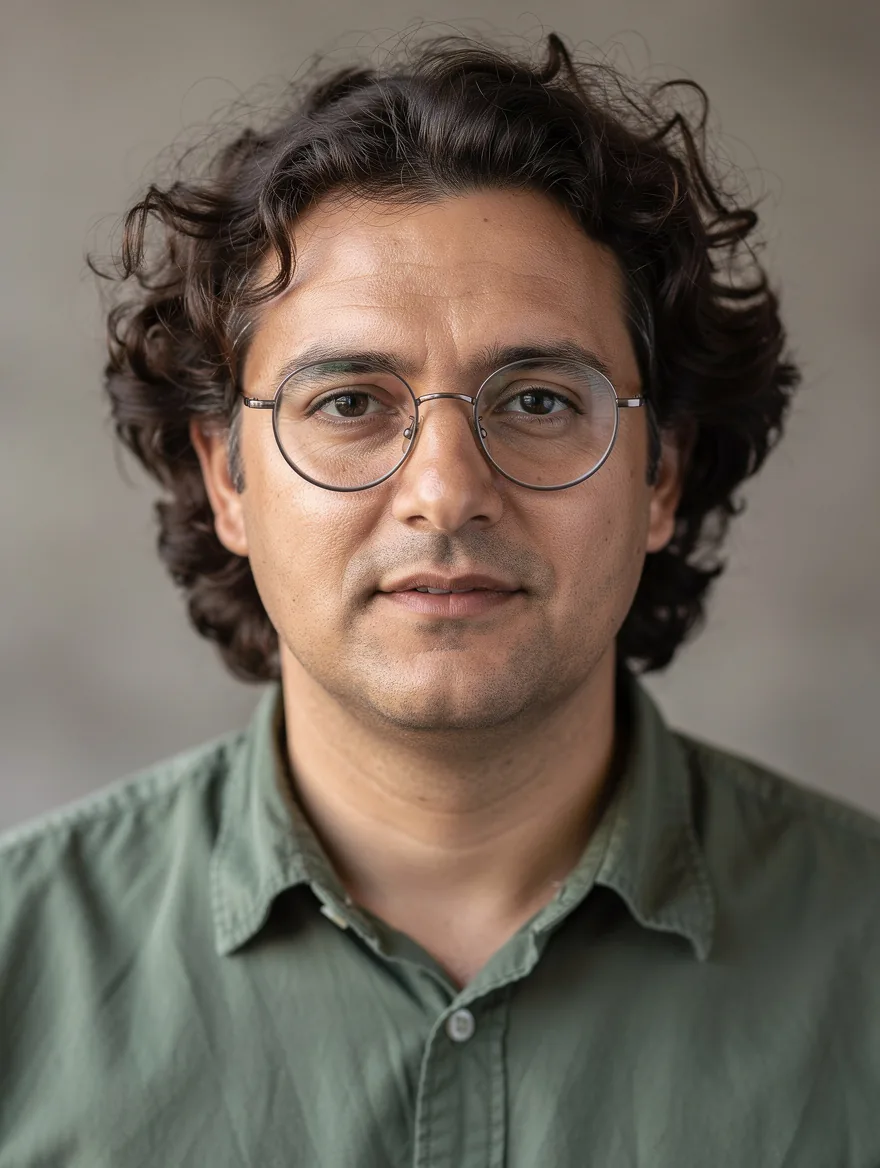 | 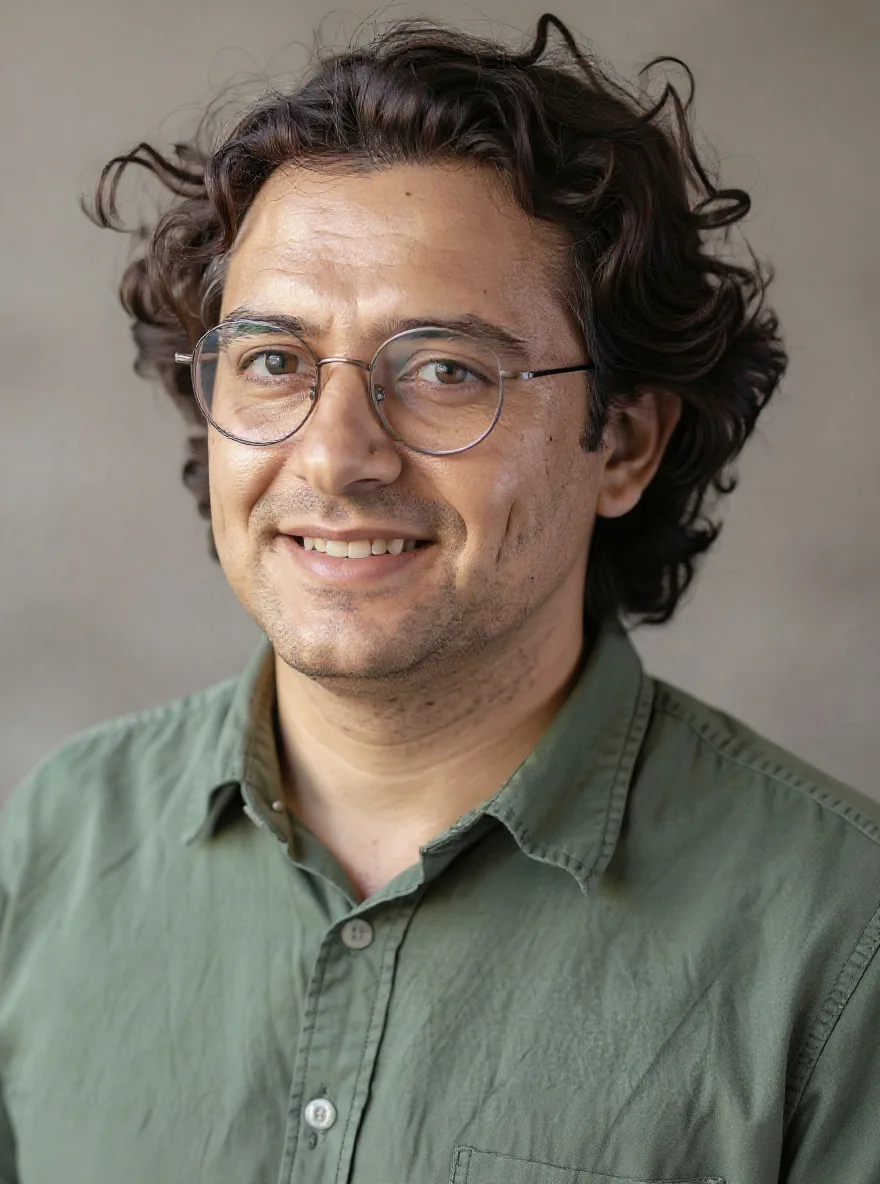 |
Left: FLUX.2 [pro] input, 880 × 1168 pixels. Center: first FLUX.1 Kontext [pro] edit, 880 × 1184. Right: second FLUX.1 Kontext [pro] edit, 880 × 1184. Both edits used default output sizing.
The subject remains recognizable, with dark curls, round metal frames, a green collared shirt, and a plain gray background. Both eyes remain visible after the turn. The second edit raises his cheeks and adds a smile while keeping a similar head angle.
Two details miss the instructions: the head turns toward the picture’s left edge, which is his right, and the smile exposes teeth despite the closed-mouth request. If both details matter, this result needs another edit.
How can you continue an edit on flux-3image?
Select FLUX.1 Kontext [pro], upload one photo, and describe one change plus the details to retain. For the next edit, upload the result you want to continue from. BFL’s Kontext editing documentation illustrates the same sequence.
As of October 2026, the live pricing page lists Kontext [pro] at 4 credits per image at 1K. If you need multiple references or 2K or 4K output, the FLUX 3 Image editor supports up to 10 references and 1K, 2K, or 4K output.
For a local edit, the Kontext object-removal example shows a mug removal and the surrounding table detail that changed with it.